Migrating the blog to Nikola
New static site generator: Nikola
After a long while, I decided to start writing in this blog again, but I was not happy with Pelican, the static site generator I was using before. So I started shopping arround for something more to my liking. In the end I decided to give Nikola a try.
The best feature I've seen is the much better command line tool to manage the site. Both Pelican and Nikola provide a command to generate the site, but the diferences are stiking. In Pelican, the CLI tool generates the static site and provides a basic HTTP server so you can test the site while writing, not to mention the configuration, which requires different config files for development and publishing.
Nikola on the other hand, adopts the command <verb> format that became so popular this century (it's
the same paradigm used by other popular tools like git, docker, openssl, etc.). This tool has verbs
to help set up a website, start new posts/pages with metadata pre-filled, publish the site, manage plugins
and themes, and other goodies.
Well, this is it. Hope you enjoy.
Listing non-root users with shell
Listing non-root users
This is a simple Bash script to list all non-root and non-system users in Linux. Those users
are determined by two settings, UID_MIN and UID_MAX, found on the /etc/login.defs
file.
#!/bin/bash -
#===============================================================================
#
#          FILE: lista-users.sh
#
#   DESCRIPTION:
#
#        AUTHOR: Nerdeiro da Silva <a n a r c h 1 5 7 a  at  n i n j a z u m b i . c o m>
#       CREATED: 01/08/2023 14:14:18
#      REVISION:  0.01
#       LICENSE: GNU GPL 2.X (https://www.gnu.org/licenses/old-licenses/gpl-2.0.html)
#===============================================================================

set -o nounset                                  # Treat unset variables as an error

# Get lowest and highest UID from login.defs
export min_uid=$( awk '/^UID_MIN/{print $2}' /etc/login.defs )
export max_uid=$( awk '/^UID_MAX/{print $2}' /etc/login.defs )

# Use Awk expresisons to list only users between those limits
USERS=( $(awk -v min=${min_uid} -v max=${max_uid} -F: '$3 >= min && $3 <= max { print $1}' /etc/passwd ) )

echo "Users :: ${USERS[@]}"
echo
# Example for loop to do something for each user
for U in ${USERS[@]}; do
    USR_DIR=$(awk -F: -v usr=${U} '$1 == usr {print $6}' /etc/passwd)
    if [[ -d ${USR_DIR} ]]; then
        echo "User: $U; Directory: $USR_DIR"
    fi
done
Syncing game saves with almost any cloud service
Edit: New version of the script
Check the repository on https://gitlab.com/Nerdeiro/game-cloud-sync and follow the README.md there.
Sync your games to (almost) any cloud service
This is a simple Bash script to sync your game-saves with pretty much any cloud storage service out there. It uses Rclone, which supports dozens (not hyperbole) of providers.
The motivation to create this script was to sync my copy of Stardew Valley between my desktop and my Steam Deck. But wait, doesn't Steam do this ? Yes, it does, for copies bought on Steam. But my copy is from GOG... It runs just fine on the Deck, regardless if it was installed from a manual download, with Lutris or Heroic, it only lacks cloud saves.
This is where this script and Lutris come in. The role Lutris will play
here, is to allow us to run a script both before and after running the game, all without having
to change the default start.sh lancher script that the GOG installer creates.
What you need to use this script
In no particular order:
- Lutris (optional but recommended)
- Rclone
- A cloud service supported by Rclone
- A working remote configuration in Rclone
If you're syncing between two computers, getting Lutris and Rcloneis as easy as installing them using your distro's package manager. On the Steam Deck, Lutris have to be installed using Flatpack, after changing to Desktop mode. Rclone is a little bit more challenging, since it's not on Flathub and the Deck ships with a read-only Root (/) file-system, so using Pacman to get it is not an option.
Thankfully, the creators of Rclone have a statically compiled binary on the official website,
which means you can run it on the Deck without any issues, only you'll have to put it
somewhere on the $HOME directory. To avoid having to fiddle with the $PATH, I recommend
that after unziping the downloaded file, you move the rclone executable to a convenient
place, then edit the script to point the variable RC to the full, absolute path of the
binary.
After installing Rclone, follow the official documentation to create a configuration for your
remote cloud service. It's important that you can successfuly run a copy or sync between the
two sides. Lets say that you run rclone copy mycloud:somedir/ ~/tmp/someotherdir, if the
command finishes and the files show up in ~/tmp/someotherdir, then you're good to go.
Getting the script
Just clone it from my Gitlab Repo at https://gitlab.com/Nerdeiro/game-cloud-sync. You can do it with the command
git clone https://gitlab.com/Nerdeiro/game-cloud-sync.git
Once it's cloned, you can use it right away, on a normal Linux distro. To put use it on a Steam Deck, before transfering a copy to the console, open it in your favorite flavor of Vim and find the line:
RC=$(which rclone)
and change everything after the equals sign for the full path to the Rclone binary that you downloaded before. It should look like:
RC=/home/deck/bin/rclone
or something like that.
Using the script on the command line
Just run it with the following options:
- -s : Source. It can be a local directory or an Rclone remote
- -d : Destination. It can be a local directory or an Rclone remote
- -v : Verbose. Shows the copy progress on the terminal
One of the parameters should be the local directory where your save games are, eg. $HOME/.config/StardewValley, the other
should be a remote configuration and path, like mycloud:/StardewValley. Which one you'll use with -s or -d will
depend on which direction you want to sync, to or from the cloud.
Using the script with Lutris
Open Lutris and click with the right mouse button on your game, selecting "Configure" to show the screen bellow:
If your screen is not like that, tick the option "Advanced" on the top of the dialog, then scroll all the way to the botton of the "System Options" tab. There you'll the boxes to configure a Pre-launch and a Post-exit scripts.
To download the save files from the cloud to your computer (or Deck) fill the "Pre-launch" line with:
sync-game.sh -s my_cloud:saved_games/ -d $HOME/game_dir/
To upload the save files from the computer to the cloud, fill the "Post-exit" line with:
sync-game.sh -s $HOME/game_dir/ -d my_cloud:saved_games/
If everything works as they should, your game should be saved on your cloud storage, ready to sync to other devices. Do the same on the Steam Deck if necessary.
And happy gaming.
Using Home Assist to sleep/resume a Linux PC
Intro
All right, you automated lots of stuff arround your place with Home Assistant, but what about your PC ?
Wouldn't it be cool if you could turn it on or off from anywhere, just tapping on a button in your phone screen ?
Well, if your PC supports Sleep/Resume, you can do it with a couple of scripts. I'll demonstate here how to do it for a Linux desktop/notebook. You can addapt this to MacOS, maybe even Windows. You you do it, let me know on Mastodon, just Toot me at @nerdeiro@fosstodon.org.
Checking system
First of all, let's check if your system supports Sleep/Resume. On a laptop, this is pretty much a given, but on a desktop, it may not be enable on the BIOS settings. Run the command bellow to check it:
$ cat /sys/power/state

freeze mem disk
If you get this response, your system supports S3 sleep. Good. If not, check your BIOS settings. Since each mother board maker have different menus, I can't help you that, sorry.
Second, to wake up the system, it'll be necessary to enable Wake on Lan (WoL) too. This is another BIOS setting the you need to check, keep in mind that some board makers (Like Asus), might not have an explicit "Wol" or "Wake on Lan" setting, in Asus boards you need to activate a setting that says "Power On By PCI-E".
Now, to make WoL work, you're have to find what is your actual MAC Address. It is possible to use a custom MAC when the system is up and running, but the system is on S3 (Sleep) state, it's the BIOS that will answer to the "Magic Packets", using the factory assigned MAC. Fortunatelly, using the ip command in Linux, we can figure this easily:
$ ip link show

2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1420 qdisc mq state UP mode DEFAULT group default qlen 1000
    link/ether xx:yy:de:ad:be:ef brd ff:ff:ff:ff:ff:ff permaddr xx:yy:zz:aa:bb:cc
The address after 'permaddr' is your factory assigned MAC. Write it for later.
Remote scripts
Now, let's prepare the scripts that will do the magic. SSH to your Home Assistant box, if HA is running on a container instead of a as stand-alone OS, make sure you're comfortable with Docker's or Podman's commands, because you're gonna need to do some restarts.
Now, let's see what our scripts look like, before deploying them to HA.
The suspend script
This is the script that should put the machine to sleep:
#!/bin/bash -

ssh -t -o StrictHostKeyChecking=no -o UserKnownHostsFile=/dev/null \
    -i /config/keypair nerdeiro@192.168.1.2 \
       'logger "Sent to sleep by Home Assistant"
        sudo systemctl start suspend.target'
A little bit of explanation about the script. Since it's supposed to run a command using sudo (see bellow why), we need to run SSH with -t option, so it creates a pseudo-TTY on the other side, or it will fail, then since we don't want to deal with SSH known hosts stuff, We tell it to ignore strict host checking and use /dev/null instead of $HOME/.ssh/known_hosts.
After that, we have the private key used to authenticate in the target box, the user and host and the script itself. This is where you should be asking "Hey, but what if the IP address changes ?". Well, make sure it doesn't. Either configure a static IP on your machine, or set up your DHCP server/WiFi router/whatever to always assign the same IP to you, based on the MAC Address. In my case, the DHCP server that distributes addresses on my LAN is a Pi-hole, which you should be using anyway to block ads and trackers.
Then the script that will run on the other side. In this example, it's a two-liner because I added a line to generate a syslog message with logger. If you just want the suspend command, there's no need to put it between single quotes. For multi-line scripts, that's necessary.
Now, you might be wondering, why use sudo with systemctl to start the suspend target ? I don't need it locally ! The answer for that is polkit, which has a local agent that authenticates you and lets you suspend the machine without explicitly using pkexec or sudo, but since polkit agents don't work over SSH (maybe they do, but my DuckDuckGo skills failed me this time), we'll have to use good old sudo instead.
Now, let's deal with authentication on the machine we want to suspend. Putting your password on a script is a bad idea and it's cumbersome to use, so a key-pair is the way to go. So, SSH to the machine running Home Assistant and create a new pair of keys there. If you're running HA on a container, you should have a directory somewhere that is mounted as a volume under /config inside the container. You can even do this from inside the container itself. Run docker ps, get the name of the container (let's say it's called "homeassistant") and run docker exec -ti homeassistant bash. This should put you right at the /config directory inside the container. If your HA is a stand-alone OS, once logged into it, change to the root user with sudo su - and cd /config. Creating a key-pair is as simple as running ssh-keygen -t ed25519 -f /config/keypair and pressing Return a couple of time to leave the password empty. If you prefer RSA keys, intead of ED25519, just remove the -t ed25519.
Once you have the key-pair, copy the contents of the file ending in .pub to the target machine and add it as a line in $HOME/.ssh/authorized_keys. Try SSHing to your PC from inside HA-OS or container using this key, just to confirm everything is OK before proceeding.
The resume script
This is the one that wakes uo your machine:
#!/bin/bash -

wakeonlan -i 192.168.1.255 xx:yy:zz:aa:bb:cc
This is a very simple one. We don't even need to worry about installing the wakeonlan command, as it's already provided on the Home Assistant container/OS. The only thing you should change here is the network broadcast address and the MAC Address your your PC. To find what the broadcast address is, run the command:
$ ip address show

2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1420 qdisc mq state UP group default qlen 1000
    link/ether xx:xx:de:ad:be:ef brd ff:ff:ff:ff:ff:ff
    inet 192.168.1.2/24 brd 192.168.1.255 scope global enp4s0
       valid_lft forever preferred_lft forever
The broadcast address is the one right after brd on the 3rd line.
You can test if its working, as long as you have some other device that can SSH to Home Assistant. Put your PC to sleep, then from HA, run the wakeonlan command like in the script. If the PC turns on, we're set. If not, make sure that the machine supports this feature, same for the network card, if it's an add-on, and your BIOS is properly configured.
Home Assistant setup
All right, lets get to the good part. Setting up Home Assistant itself.
Before we start pushing the mouse on the GUI, there are a few configurations we need to do, to tell Home Assistant the scripts exist. Locate whre the file configuration.yaml is. If you're docker execing into the container or SSHd to the HA-OS, it'll be located in /config, if you're outside the container, check in docker which directory is used as the /config volume.
Create both scripts on the /config directory, making sure they're executable, run chmod 755 script if neccessary. Run each of them from the CLI, just to be sure they work.
Now, open up configuration.yaml on your favorite editor, such as Vim or Nano, and add this lines:
shell_command:
  sleep_script: /config/sleep.sh
  wake_script: /config/wake.sh
Listing them as shell commands in configuration.yaml will create the services that can be run, but to add them as buttons on a dashboard we need to create them as script entities. If you look at the configuration, you should see a line like:
script: !include scripts.yaml
So, save the configuration file and open scripts.yaml on your editor. Don't worry if it's empty, just add the following lines to it:
pc_sleep:
  alias: pc_sleep
  sequence:
  - service: shell_command.sleep_script
    data: {}
  mode: single
pc_wake:
  alias: pc_wake
  sequence:
  - service: shell_command.wake_script
    data: {}
  mode: single
Those will tell Home Assistant that they exist, so we can set them up on the GUI, which is the next step. So, save the files and restart Home Assistant, either by rebooting the server if it's an OS install or by restarting the container. After that, log on to the GUI and lets create some buttons.
Creating buttons
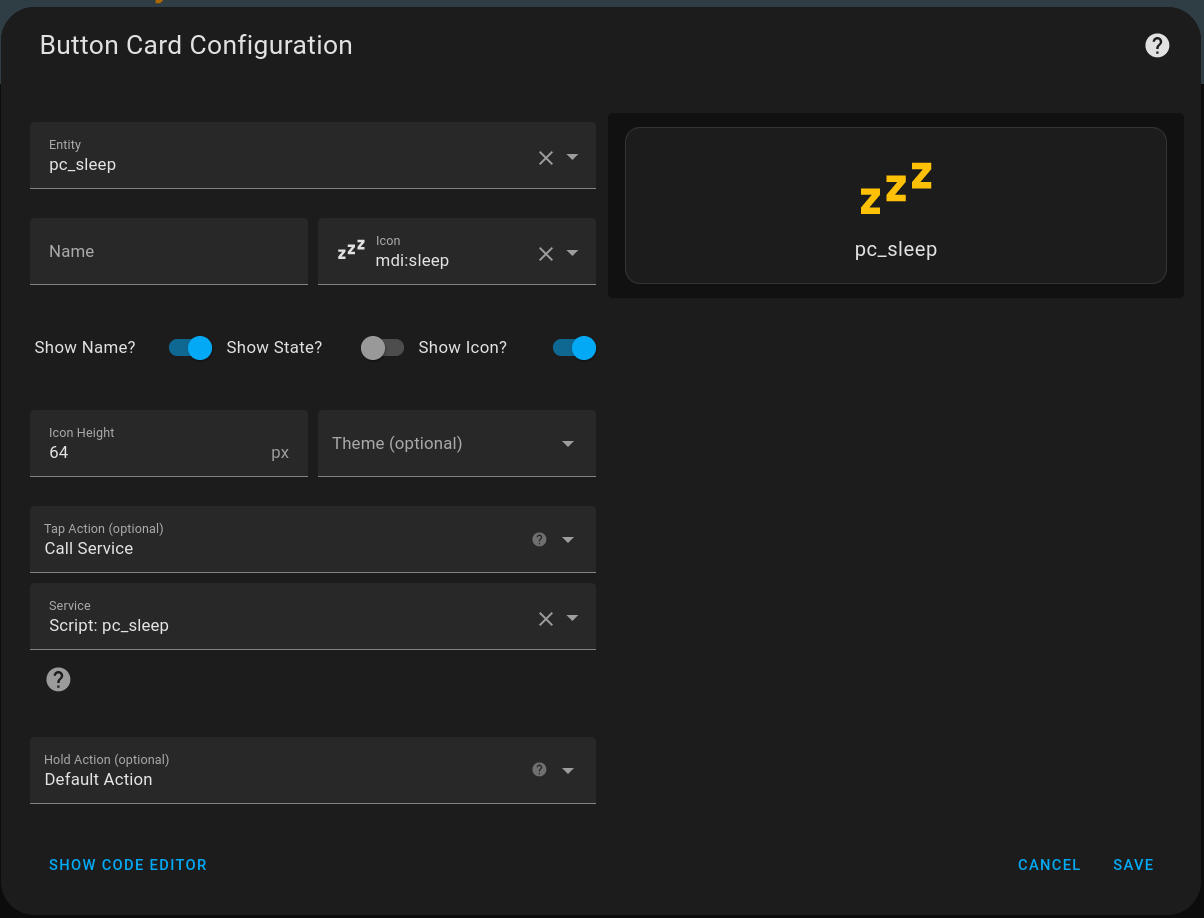
On the Home Assistant GUI, chose the dashboard where you want the suspend and resume buttons to be and click on the "hamburger" menu, it should be on the top-right of the page, and chose Edit Dashboard. Then click Add Card and chose "Button". Fill in the following:
- Entity: Select one of the scripts we created (e.g. script.pc_sleep)
- Name, Icon, etc.: It's up to you how it would look like.
- Tap Action: Select Call Service
- Service: Again, select the script you want to run.
It should look like this:
Testing the setup
I made a small video showing it working:
By now, you too should have the capability to sleep/resume your PC from anywhere, even your bed, so no more worries if the computer was left on or not. Just reach to your phone and turn it off.
Well, this was a long one, so happy automations and see you on the next one.
Running Ansible with AWS System Manager
Introduction
Ansible is a fantastic tool to automate tasks and manage fleets of servers
Amazon SSM, or Systems Manager, also offers tools to manage your fleet of servers. One of the tools they offer is Session Manager, which allows you to run an interactive shell without having to open a TCP port to the world or dealing with SSH keys.
Usualy, ansible uses SSH to connect and send payloads to the managed servers, if you're using only SSM to mange your instances, how can Ansible connect to them? Well, by using SSM itself to communicate and an S3 bucket to store the payload.
Debian/Ubuntu users beware
System Manager uses a small script to determine if the connection was sucessfull, by watching the results on Stdout/Stderr. Problem is, they specify /bin/sh as the shell, only to use some Bash specific syntax on it. This is a problem for Debian based distributions, because by default, they symlink /bin/sh to Dash, instead of Bash. Since Dash doesn't support the Bashisms that AWS uses, it will return an error. The best way to fix this, is run a script using SSM to re-link /bin/sh to Bash instead.
As root, run this script on all your Debian instances to change it:
#!/bin/bash
echo "dash dash/sh boolean false" | debconf-set-selections
debconf-show dash
DEBIAN_FRONTEND=noninteractive dpkg-reconfigure -p critical dash
You can do this from AWS SSM Control Pannel by selecting Run Command under Node Management and selecting AWS-RunShellScript as the document. No need to spam sudo on the script, this document runs the scripts as root by default.
After that, all scripts that specify /bin/sh as the interpreter will use Bash instead, which should not cause any more problems.
Preparation
To do that, we need to first make sure all the instances that will be managed can be accessed with SSM. All of them will need an IAM Role with SSM permissions, in addition to that, we need a S3 bucket that the instances can aread from too, so the IAM Role would also need at least read permission on the bucket. This can be acomplished by adding the appropriate permission to the IAM Role attached to the instances or with a Bucket Policy. Make those settings then test them by acessing an instance using SSM, the command for that is aws ssm start-session --target <instance-id>, then use the AWS CLI tool to list the contents of the bucket with the command aws s3 ls s3://ansible-bucket/. If we succeed with the connection and listing the Buclet, we're good to go.
Ansible Configuration
Using the AWS community modules for ANsible, it's possible to get a list of all your EC2 instances and use that as an inventory. To do that, we need to enable it on Ansible's configuration. We can do that by creating an ansible.cfg on our playbook directory. Open the file and add the following lines:
[inventory]
enable_plugins = aws_ec2
Now, let's create the inventory itself. Create an YAML file, like ec2_inventory.yaml with this content:
plugin: aws_ec2
regions:
  - "us-east-1" # replace this with your region

# Example filters. Bring only running instances.
# The commented line show how to filter using a Tag
filters:
  instance-state-name: running
#  tag:OS_Type: Linux

# Example exclusion. We don't want instances running Windows Server
exclude_filters:
  - platform:
    - windows

# Building the inventory itself. This example will use the instance-id
# as Hostname. This is needed to use SSM as a cennection method.
# The keyed_groups key will generate groups based on platform details and
# Tags. This is optional.
hostnames:
  - instance-id
keyed_groups:
  - prefix: platform
    key: platform_details
  - prefix: Tags
    key: tags
Now, to test if our inventory is working, we use the command ansible-inventory -i ec2_inventory.yaml --graph. The result should be a tree graph listing all our instances.
@all:
  |--@Tags_Some_Tag:
  |  |--i-12345abcd
  |  |--i-23456cdefg
  |--@Tags_Another_Tag:
  |  |--i-567fghd
  |  |--i-9875poi
  |  |--i-4567kjb
  ...
Running a Playbook
Now lets try running a simple Playbook that colelcts minimum facts and lists the content of /etc/os-release.
---

- name: SSM Playbook
  hosts:
    - all
  gather_facts: false
  vars:
    # This is where we tell Ansible to connect using SSM
    ansible_connection: aws_ssm
    # The bucket that will be used to transfer the payload
    ansible_aws_ssm_bucket_name: ansible-bucket
    # AWS Region where the instances are
    ansible_aws_ssm_region: us-east-1
    # This is why we should use the Instande-Id as hostname, so
    # we can pass it to the SSM module using Ansible's inventory_hostname variable
    ansible_aws_ssm_instance_id: "{{ inventory_hostname }}"
  tasks:
    - name: Collect Facts
      ansible.builtin.setup:
        gather_subset:
          - '!all'
          - '!min'
    - name: Cat a file
      register: os_release
      ansible.builtin.shell: |
        cat /etc/os-release
    - name: Show the content of the file
      debug:
        msg: "os-release: {{os_release}}"
Now, we just watch the output. If everything is correct, we should see the contents of /etc/os-release from all our instances on the terminal.
I hope this mini-guide helps. Any doubts or comments, hit me on Mastodon: @nerdeiro@fosstodon.org
See you on the next one.